Have me check your AWS Cloud config

It’s 2026, and since 2012 (14 years) I am now back to independent consulting. Lets check what’s changed in the IT industry (locally, nationally, and globally), and how I have changed since I was last available for short term engagements:

Globally: Cloud & IT

AWS continues to dominate the global cloud hyper scalar field, which in 2012 was almost exclusive to AWS. Its grows in size with the number of services, and the number of regions.

In early 2012, there were just 7 AWS Regions active: US-East 1, US-West-1, Dublin, US-West-2 (Oregon), SA-East-1 (Sao Paulo), AP-Northeast-1 (Tokyo), (ap-southeast-1 (Singapore). Today in 2026 there are 39 – over 5 times as many.

Back then Local Zones, which are Availability Zones that are considerably distant from their controlling Region and often have limited cloud managed services available compared to standard AZs, did not exist: now there are more then 30, bringing low latency between additional population centers to EC2 compute and some additional services.

On the flip side, in 2012 it was unheard of to hear about two things: price rises, and service terminations.

It was often highlighted that the original key-value store service, SimpleDB, was still operational. It was eclipsed by Dynamodb in almost all measurable ways, but the point was that the original SimpleDB service was still operational; clients that had depended upon it in 2007 could continue to do s

However for other AWS services, this has seen them come and go. For most of these, this is acceptable, particularly if they had been ended before organisations came to be largely dependant on them, or if there was a seamless transition to a suitable replacement. Anything else is work for clients to do, which is cost to adopt a change.

Of course, we have also seen industry fads come and go: blockchain, IoT, digital twin, metaverse. The volume of messaging around these have been distracting from the value of many systems. Organisations paid huge sums for virtual digital reality in the metaverse – all of which is practically worthless because, as we discovered with 3d TV in the 1990s: no one wants to wear an expensive 3D headset all day.

Nationally: Cloud & IT

In Australia, the launch of the AWS Region in Sydney at the Customer Appreciation Day in 2012 was huge. I spent time working at AWS on the global compliance board, selecting the industry validations that would become critical: key amongst this at the time was IRAP for the Australian government.

The day AWS opened, with its at-the-time cost focus on data transit, dropped the previous days industry rate by almost half. Incumbent telco carriers had been charging vast amounts, and AWS cut that bill down just by existing.

Throughout this period many government services digitised, and the increased online spend, versus clicks and mortar shopping malls continued to rise. Today sees vastly increased courier delivery services, much reduced postal letter service (just send an email/text), and much lower footfall in most retail spaces.

Even in major city centres, the retail sectors are seeing reduced sales, and increased retail property vacancies. Those vacancies become a flywheel, as more organisations leave, less shoppers want to visit those locations, and so more retails exit the space.

Buoyed by the national broadband network, we’ve seen Australia remove most analogue last-mile connections; the kind that used to have a voice circuit, and perhaps a DSL channel. The data volumes and number of digital devices online in the home have also increased (link):

YearAverage Monthly Household DownloadsAverage Connected Devices per Home
2013~40 GB7 devices
2019~250 GB17 devices
2023~443 GB22 devices
2025/2026~508 GB25 devices

All of those devices are talking to some digital backend. Australian Bureau of Statistics (ABS) claims around 10.9 million households, which would but that at around 272.5 million devices all up. Each one of those devices is getting data from, or sending it to, somewhere – and that’s often the largest most cost effective cloud provider, even if it gets down-streamed to other locations later.

The ABS itself, in charge of the Australian Census, has moved to AWS for the last few, following the disaster using IBM SoftLayer in 2016, an event later dubbed #CensusFail with the capacity overload triggering insane reactions of hacking from other nation states when it was really that … the engineering was unacceptable. Several things have changed this then: one, they allowed people to complete the census over an extended window instead of everyone on the same 4 hour evening, and second: they moved to AWS.

Locally: Cloud & IT

When I opened the AWS office in Perth in April 2012, there were two people. Today there are hundreds.

The AWS Local Zone opened in Perth in January 2023, conjoined to the Sydney Region. AWS also opened local Direct Connect (fibre) interconnect service in Perth, helping dramatically cut the cost of private connectivity (by more than 10x).

My skills growth

When I first achieved the AWS Solutions Architect – Associate certification in January 2013, I was in the initial cohort at AWS to achieve this. Today I still hold this AWS Certification (and 8 others), revalidated over the years with re-certification. From what I am aware, I am the only person from that initial cohort to still have that certification, making me the longest certified person in the world.

I spent some time over the period expanding this, and serving as a Subject matter Expert helping write the AWS questions for their certifications.

For much of the last 10 years, I have spent a fair bit of time focusing on soft skills: collaboration, engagement, retention, planning training and upskill for thousands of engineers. My leadership style was always to lead-from-the-front, earning the trust and respect of the engineers, showing them that I can do the job, and direct it — unlike many others who direct without being able to do – career managers who don’t directly understand the depth, complexity, constraints and cognitive effort to shape and secure reliable digital systems.

One key aspect has been facilitating and pushing the sharing of knowledge. This works well to ensure continuity in the face of change. When organisations don’t value that approach, we often see system failure, compliance issues, interruption of service or other symptoms where digital systems that were once well-maintained, become rigid and dormant.

The Well-Architected Journey

In late 2014, while at AWS, I was asked to participate in defining some concepts to help AWS cloud customers navigate the problem of having too much choice in AWS.

There’s More Than One Way Do To It was a Perl developer saying, and this became true in AWS as well. There had to be some level of balance.

What we came up with was 5 pillars of Well-Architected. This framework was initially for AWS’s own Solution Architect teams to use, but became public in 2016 as a concept, complete with the concept of a Well-Architected Framework Review, a consulting service where independent services partners could bring their smart people in to a client, offer that advice, and provide the client with visibility as to what they could modify to get further benefit.

The balance of priorities was something I took to my AWS cloud engineering teams in global practice starting from my first day in 2014. It helped guide architecture for services that not only optimised cost, but exceeded the expectations for reliability and scalability, including during a complete Availability Zone outage in 2016. When other large organisations were being paraded on the nightly news for their outages, my clients were continuing unabated.

Available Now for you

So what can (or should) I do with nearly 16 years of cloud architecture experience, a spell as the security solution architect for AWS for all of Australia & New Zealand, longest-certified person in the world, certification SME on many AWS certs, former AWS practice lead (and partnership global alliance lead)? Couple that with three decades in Linux, Open Source, Networking (including founding Australia’s premier non-profit for internet advocacy and industry connectivity services (link)?

I am available for Well-Architected Framework Reviews of client environments. I am happy to come on site to your location and work with customers existing teams, helping identify the opportunities for improvement. Not only do we walk through the focus pillars of the Well-Architected tool, but also do some high level network security observations, and help identify tasks and direction that will help yield long term success.

I am also available for advisory work, should you need a senior experienced engineer who can help provide clarity around Cloud and modern technology operations.

While I am in Perth, Western Australia, I am open to clients across Australia, or worldwide. De plus, je parle français, ce qui couvre également tous les pays francophones.

For more information, check out https://nephology.net.au/, and please have an obligation-free chat with me. Email is on the Nephology website (though I suspect many of you have me on LinkedIn or my direct mobile in your address book).
A new class of AWS Certification

AWS announced today not just a new AWS Certification, but a new class of certification: Business. The specific certification is called the “AWS Certified AI Business Strategist – Business”.

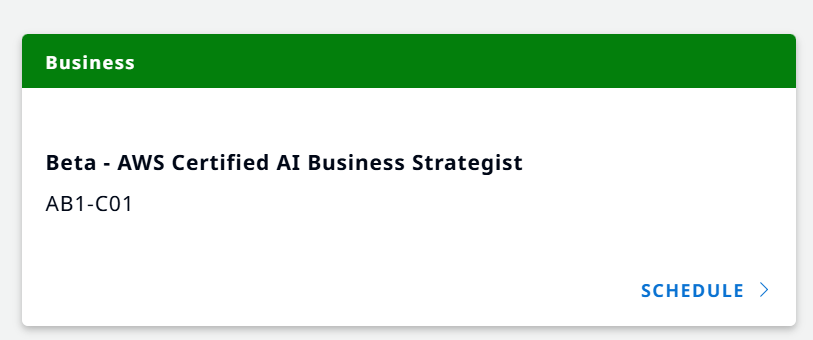
This certification is open in beta now, as can be seen from the Cert Metrics portal:

Until February 2027, this USD$100 certification is half price to US$50. AWS claims no technical experience is necessary, and this certification is suitable for roles that are “Product and program managers, sales and business development professionals, line-of-business leaders, consultants and business analysts, marketing professionals”.

This brings back to 12 the number of available AWS certifications:

  • Foundational (2):
    • Cloud Practitioner
    • AI Practitioner
  • Associate: (5)
    • Solution Architect
    • CloudOps (was SysOps)
    • Developer
    • Data Engineer
    • Machine Learning Engineer
  • Professional (3):
    • Solution Architect
    • DevOps Engineer
    • Generative AI Developer
  • Specialty (2):
    • Security
    • Networking – was to be retired already, now retirement rescheduled to December 2026

Given a new class of certification, we can perhaps expect to see more certifications in the category. There’s long been rumours (circling back over 6+ years) of a FinOps certification that’s not seen the light of day yet – perhaps that would fit in this class.

As noted above, the Networking – Specialty certification was recently given a slight reprieve from being axed. It had been announced it was ending 25 August 2026, but that’s pushed out to 31 December 2026. AWS Networking is continuing to evolve and expand – particularly with managed interconnect to alternate hyperscaler cloud providers. Many comments I have seen are from engineers who feel that the content in this certification is important, and not covered by any other certification, and that remove this would be a loss, to which I agree. However, I am biased as I have contributed many questions to this certification over the last decade as one of the volunteer AWS Certification Subject Matter Experts.

Some questions I have from this:

  • With 12 certifications back available, does this restore the golden jacket requirement to be “all 12” again?
  • Does achieving the AI Strategist – Business certification re-certify and extend any Foundational certifications the person may have (eg Cloud Practitioner)?

As always, there is a set of AWS certifications for each audience in an organisation, and I don’t expect most people to go and achieve all of them – but the subset that are most applicable to their role.

The importance of time in networks

Last week saw a major incident for an Australian telco that literally stopped trains, business, and other services across Australia. After a week it was revealed that the company’s internal time servers had not been well maintained, and flipped over 19.x years of uptime, causing them to warp back in time20 years.

Apparently it was a known issue; engineers had warned about it, the vendor had many outstanding updates to be applied. But these devices had just been kept up and running.

There were multiple of them, but when operations teams are stripped down, clearly what should be essential maintenance just doesn’t happen.

The original Network Time Protocol (NTP, and the newer Precision Time Protocol (PTP) is one that often originates from atomic clocks. One readily available source is from GPS satellites, happily blasting the time across your location routinely. These days that’s also joined by Europe’s Galileio, the Russian GLONASS, and CHina’s BeiDou.

And while you think the correct time is universal these days (check your mobile/cell phone – you probably find it has the right time), these signals are often jammed and interferredwith by various national entities during conflicts and other activities to confuse positioning systems. Yes, it’s like the plot of James Bond’s Tomorrow Never Dies.

In every network I have ever had, pre cloud or post cloud, having a reliable source of time was always critical. Logs must line up to the millisecond, if not then more precise than that.

Having scalable time services is even more important, because at scale you are relying on correct time even more. Most network operators normally have multiple time servers, listening to upstream time providers, locate din different buildings, on different UPS, or in different data centers, etc..

In order to protect their primary time servers, organisations then have a second level of server, available to clients – these are the only ones that can talk tot he primary server. If you’re using NTP, then the Stratum number will help show this, as eveerly level down (away) from the atomic clock is a higher stratum:

  • Stratum 0: the atomic clock
  • Stratum 1: the server physically wired to the atomic clock
  • Stratum 2: downstream from the Stratum 1 servers
  • etc….

On my small Debian system, I have the SystemD NTP service (timesyncd) that is listening, and I can see from the comment timedatectl show-timesync the current status:

# timedatectl status
Local time: Mon 2026-07-13 22:51:00 AWST
Universal time: Mon 2026-07-13 14:51:00 UTC
RTC time: Mon 2026-07-13 14:51:00
Time zone: Australia/Perth (AWST, +0800)
System clock synchronized: yes
NTP service: active
RTC in local TZ: no
# timedatectl show-timesync
FallbackNTPServers=169.254.169.123 fd00:ec2::123
ServerName=fd00:ec2::123
ServerAddress=fd00:ec2::123
RootDistanceMaxUSec=5s
PollIntervalMinUSec=32s
PollIntervalMaxUSec=34min 8s
PollIntervalUSec=34min 8s
NTPMessage={ Leap=0, Version=4, Mode=4, Stratum=3, Precision=-18, RootDelay=198us, RootDispersion=335us, Reference=A9FEA97A, OriginateTimestamp=Mon 2026-07-13 22:39:05 AWST, ReceiveTimestamp=Mon 2026-07-13 22:39:05 AWST, TransmitTimestamp=Mon 2026-07-13 22:39:05 AWST, DestinationTimestamp=Mon 2026-07-13 22:39:05 AWST, Ignored=yes, PacketCount=1166, Jitter=489us }

Here my internal NTP daemon is a Stratum 3, which means there is a Stratum 2 and 1 above me. IN this case, you can also see the address being used: 196.254.169.123 – which is the AWS Time Sync Service, a scalable time source across the entire EC2 fleet. In pre-cloud days, I would have two or more NTP hosts exchanging NTP traffic direct to upstream peers, and then have hundreds of servers query those three.

I would also have monitoring on those to ensure that the the three had a reasonably consistent view of the current time, and were not drifting off into the past (or future).

And lastly, the NTP software would be some of the core packages to get routine package updates to address vulnerabilities and bugs over time. You would do these one at a time, to ensure the other NTP servers remained available, and the one being updated had time to reconnect, sync up, and start having (even network-internal) clients use it.

Not maintaining hardware (firmwares) is a clear piece of not taking the responsibility for basic operational defence of these systems. Once upon a time (30+ years ago) a long “system uptime” was an admired feat of endurance. For the last decade, I looking at the age of your software (and firmware) to determine the oldest pieces and prioritising everything having a low median age is a better measure. Something that has been unpatched, but still running, doesn’t mean it is secure and reliable. If it hasn’t been restarted in the last year, do you know if it can restart after a power outage? Does it have patches that are not yet available? We know that cryptographic support changes over time (see TLS 1.3), but so has basic networking addressing protocols (see the IPv4 and IPv6 changes).

A ton of IPv6 innovations in AWS

The last three months have seen a large number of IPv6 announcements from AWS. I’ll recount some of them here:

  • Organisations support IPv6 (link)
  • IPv6 for EC2 public DNS names (link)
  • Transfer family supports IPv6 (link)
  • Managed Service for Apache Fink adds IPv6 (link)
  • Resource Groups adds IPv6 support (link)
  • EFS supports IPv6 (link)
  • EFS supports IPv6 (link)
  • Private CA supports IPv6 (link)
  • Site-to-Site VPN supports IPv6 on outter tunnel endpoints (link)
  • DataSync supports IPv6 (link)
  • SNS expands IPv6 support to include VPC endpoints (link)
  • SQS expands IPv6 support to include VPC endpoints (link)
  • CloudWatch adds IPv6 support (link)
  • EventBridge supports IPv6 (link)

Much of the public (Internet) facing endpoints for these services are now dual-stack, supporting both IPv4 and IPv6 (for now).

But have a think about the VPC endpoints that are now either dual stack, or IPv6 only: this increases the direct integrations for potential IPv6 only subnets, or massive sizes, to integration endpoints such as SQS and SNS. These scale-out VM farms can now have these loosely coupled integrations that can support the sale of millions of virtual machines; the rest of the VPC may be on traditional IPv4 only allocations, but having that layer of messaging is now highly valuable.

We’re at a point now where it is almost commonplace for dual-stack endpoints for most AWS cloud services; and it should be the same for endpoints that customers make on the AWS cloud. There’s very little holding you back – certainly not cost, and in some cases, cost is (or will likely be) the driving factor for the rapid uptake of IPv6, for those that are ready.

Amazon SQS adds IPv6 support

At first glance, this seems like a strange thing to be even mildly excited about.

AWS has been added “dual stack” (having both IPv4 and IPv6 addresses) for their services for some time, and I have blogged about this many times over.

First, lets just go read the brief release, from April 21 of 2025 https://aws.amazon.com/about-aws/whats-new/2025/04/amazon-sqs-internet-protocol-version-6/.

OK, you’re back. First up, how is this working?

Well, the existing API endpoints, such as service.region.amazonaws.com have been extended with a new TLD. While amazonaws.com still exists in documentation, I discovered that dual-stack endpoints are on a different domain (docs), “api.aws”:

{protocol}://{service-code}.{region-code}.api.aws

While most services do not respond to ping, its a handy way of doing a DNS resolution:

> ping -6 sqs.ap-southeast-2.api.aws

Pinging sqs.ap-southeast-2.api.aws [2406:da70:c000:40:e3db:e3b2:7e93:ef41]

Your library (eg, boto) may not be up to date with this change, and even then, this new endpoint may not be in use.

Pro Tip: always update your boto library.

So why is this useful?

Let’s say you have a workload that uses SQS, running from your existing data centre, on a traditional IPv4-only network. Your application uses SQS as a fan out mechanism to despatch jobs to a fleet of worker nodes. Historically, this set of worker nodes, when listening to SQS for messages, would have had to all used IPv4; now they can exist on IPv6 only networks, and still receive their messages.

In effect, SQS as a control mechanism can now also be a bridge between hosts on either IPv4 or IPv6.

I’ve been championing the use of IPv6 with, in and on AWS since 2012; this year (2025) has continued to see additional services – like this – step up to include seamless dual-stack capability. At some stage, this will become table-stakes, required on service launch, and not a future service innovation.